Title tags remain the highest-leverage lever in SEO because they are the only element that simultaneously influences both ranking algorithms and human click-through behavior. For enterprise sites or large-scale publishers, testing titles one by one is a recipe for stagnation. To move the needle on a domain with thousands of URLs, you must shift from individual page optimization to algorithmic pattern testing. This requires a transition from "best guesses" to a rigorous framework of statistical significance and automated deployment.
Segmenting Your Site for Templated Testing
You cannot effectively test 50,000 product pages individually. Scaling requires grouping pages into logical buckets based on their template and intent. If you change a title pattern on 500 category pages, you are testing the template, not the specific keywords. This aggregation provides the data density needed to reach statistical significance faster.
Best for: E-commerce sites, directory sites, and large-scale affiliate hubs where pages share a common structure.
- Category Pages: Test "Best [Category] of [Year]" vs. "[Category]: Buy Online & Save."
- Product Pages: Test "Price-first" vs. "Feature-first" title structures.
- Editorial Content: Test "How-to" vs. "Numbered List" vs. "Question-based" titles.
By segmenting your site, you isolate variables. A title change that works for a "Best of" listicle may fail miserably for a product SKU page. You must treat these segments as independent testing environments.
The Methodology: Split Testing vs. Time-Series Analysis
Most SEOs rely on time-series analysis: they change a title, wait two weeks, and look at Search Console. This is fundamentally flawed because it ignores seasonality, algorithm updates, and competitor moves. If your traffic goes up, was it the title or a competitor losing their rankings? You don't know.
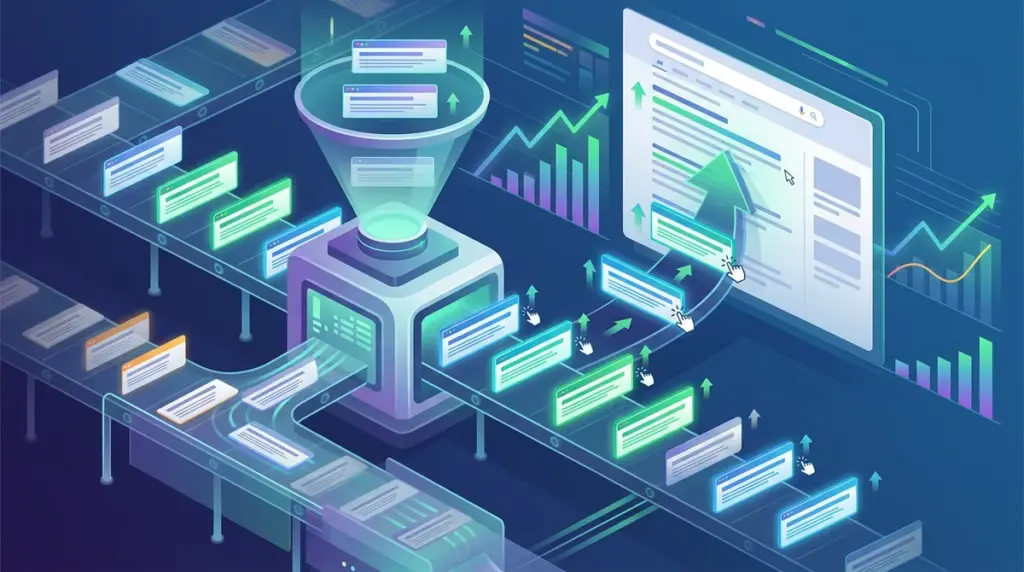
True scale requires Split Testing (A/B Testing). In this model, you take a group of 1,000 similar pages, keep 500 as the control group (no change), and apply the new title pattern to the other 500 (the variant). By comparing the performance of the variant group against the control group over the same period, you negate external noise. If the variant group sees a 12% lift in CTR while the control group stays flat, you have a verified winner.
Normalizing for Position Decay
CTR is inextricably linked to position. A title that gets a 10% CTR at position #1 is performing poorly, while the same CTR at position #5 is legendary. When running tests at scale, you must use a CTR decay curve to normalize your data. This involves calculating the expected CTR for every position on your specific SERP and measuring the "lift" above that baseline. Without this normalization, your data will be skewed by natural ranking fluctuations that have nothing to do with your title tag.
Technical Execution via Edge SEO
The biggest bottleneck in SEO testing is often the development queue. Waiting six weeks for a ticket to move a title tag kills the momentum of a testing program. To run tests at scale, use Edge SEO tools like Cloudflare Workers or Akamai EdgeWorkers.
These tools allow you to intercept the request at the "edge" (the server closest to the user) and modify the HTML before it reaches the browser. You can programmatically swap titles for specific page groups without touching the underlying CMS. This allows for rapid deployment, instant rollbacks, and the ability to run complex experiments that would otherwise be technically impossible in a legacy environment.
Warning: Google frequently rewrites titles in the SERPs if it deems your tag irrelevant to the user's query. Before declaring a test winner, use a SERP scraping tool to verify that Google is actually displaying your variant title. If Google is ignoring your change, your test data is invalid.
Measuring Statistical Significance in a Volatile SERP
A "lift" in clicks is meaningless if it is within the margin of error. For large-scale tests, aim for a 95% confidence interval. This ensures that the results you are seeing are likely due to your changes rather than random chance. Use a Bayesian statistical model to track the probability of your variant outperforming the control over time.
Generally, a test should run for at least 14 to 21 days to account for "day of the week" effects—B2B sites often see massive traffic drops on weekends, which can skew short-term data. If a test hasn't reached significance after 30 days, the change is likely too subtle to matter, or the sample size is too small. Kill the test and move to a more aggressive variation.
Analyzing the Interaction Between CTR and Rankings
A common mistake is focusing solely on CTR while ignoring the impact on rankings. In some cases, a highly "clicky" title might lose relevance for a core keyword, causing a ranking drop that offsets the CTR gain. You must monitor the net impact on total clicks.
Metrics to track simultaneously:
- CTR: The primary efficiency metric.
- Average Position: To ensure keyword relevance remains intact.
- Impressions: To detect if the title change is triggering more (or fewer) long-tail appearances.
- Clicks per Impression (Normalized): The ultimate health check of the test.
Deploying Winning Patterns Domain-Wide
Once a test reaches significance and shows a clear winner, the final step is the permanent rollout. This is where the "at scale" part of the strategy pays off. If your test on 500 product pages showed a 15% lift, you can confidently apply that pattern to the remaining 49,500 pages. This systematic approach turns SEO from a guessing game into a predictable growth engine.
Maintain a "Test Library" documenting every experiment, including the losers. Knowing that "adding price to the title decreased CTR by 8% in the electronics category" is just as valuable as knowing what worked. It prevents future teams from repeating failed experiments and helps build a site-specific playbook for creative optimization.
Immediate Action Steps for Scaling
Stop testing individual pages and start testing templates. Identify your top three page templates by traffic volume and create a control and variant group for each. Implement the changes via the Edge if your CMS is a bottleneck, and monitor the results for a minimum of two weeks using normalized CTR data. The goal is not a one-time win, but a repeatable process that continuously squeezes more value out of your existing rankings.
Frequently Asked Questions
How many pages do I need for a valid split test?
While it depends on traffic volume, a good rule of thumb is at least 300 to 500 pages per group (control and variant) to ensure that the data isn't skewed by a single high-performing outlier page.
Will changing title tags too often hurt my rankings?
Google crawls and re-indexes titles frequently. As long as you aren't removing core keywords that signal the page's intent, frequent testing (every 3-4 weeks) does not inherently harm rankings. It is the quality of the change, not the frequency, that matters.
Can I test titles on pages that don't have much traffic?
Testing at scale requires data. If your pages get fewer than 100 impressions a day, it will take months to reach statistical significance. Focus your testing efforts on high-impression templates where small percentage gains translate into thousands of clicks.
What should I do if Google rewrites my test title?
If Google rewrites your title, it usually means your tag is too long, too "spammy," or doesn't match the user's search intent. Re-evaluate the variant to be more concise or more aligned with the primary keyword's intent, then restart the test.